
Metric KPI Card Grid

Interact.js Draggable and Resizable Dashboard Panels with Snapping

Dragula Copy vs Move Lists with Spill Control

SortableJS Shared Groups: Clone from a Palette into a Page Builder

SortableJS Drag Handle with Pinned and Locked Rows

SortableJS Nested Sortable Tree with Keyboard Controls
AI Context Window Indicator — Free Token Window Usage Bar Snippet
AI Context Window Indicator · Dashboards · Plain HTML, CSS & JS · Live preview
Copy & paste
Source Code
<div class="cwi-card">
<div class="cwi-head">
<h3>Context window</h3>
<span class="cwi-model">claude-opus · 200K tokens</span>
</div>
<div class="cwi-bar-wrap">
<div class="cwi-bar">
<div class="cwi-fill" id="cwiFill"></div>
<div class="cwi-band cwi-band-warn" style="left:70%;width:20%"></div>
<div class="cwi-band cwi-band-crit" style="left:90%;width:10%"></div>
</div>
<div class="cwi-labels">
<span>0</span><span>70%</span><span>90%</span><span>100%</span>
</div>
</div>
<div class="cwi-stats">
<span id="cwiUsedLabel">84,000 / 200,000 tokens</span>
<span class="cwi-pct" id="cwiPctLabel">42%</span>
</div>
<button type="button" class="cwi-info-btn" id="cwiInfoBtn" aria-describedby="cwiTooltip">
What happens when this fills up?
<div class="cwi-tooltip" id="cwiTooltip">Once the context window fills, the assistant starts forgetting the oldest parts of the conversation to make room for new messages — long chats may lose early context. Starting a new conversation or summarizing resets it.</div>
</button>
<div class="cwi-demo">
<button type="button" data-pct="25">Fresh chat</button>
<button type="button" data-pct="78">Getting full</button>
<button type="button" data-pct="96">Nearly full</button>
</div>
</div>*{box-sizing:border-box;margin:0;padding:0}
body{font-family:system-ui,-apple-system,sans-serif;background:#0a0d15;min-height:100vh;display:flex;align-items:center;justify-content:center;padding:24px}
.cwi-card{background:#0f1420;border:1px solid #1e2536;border-radius:16px;padding:20px;width:100%;max-width:420px;box-shadow:0 20px 50px rgba(0,0,0,.5)}
.cwi-head{display:flex;align-items:baseline;justify-content:space-between;margin-bottom:16px}
.cwi-head h3{font-size:15px;font-weight:800;color:#f1f5f9}
.cwi-model{font-size:11px;color:#5b6884;font-family:ui-monospace,SFMono-Regular,Menlo,monospace}
.cwi-bar-wrap{margin-bottom:12px}
.cwi-bar{position:relative;height:10px;border-radius:999px;background:#1a2130;overflow:hidden}
.cwi-fill{position:relative;z-index:2;height:100%;width:0;border-radius:999px;background:#818cf8;transition:width .5s cubic-bezier(.4,0,.2,1),background .3s}
.cwi-fill.warn{background:#fbbf24}
.cwi-fill.crit{background:#f87171}
.cwi-band{position:absolute;top:0;bottom:0;z-index:1;opacity:.35}
.cwi-band-warn{background:#78350f}
.cwi-band-crit{background:#7f1d1d}
.cwi-labels{display:flex;justify-content:space-between;font-size:9.5px;color:#4b5675;margin-top:5px}
.cwi-stats{display:flex;align-items:center;justify-content:space-between;font-size:12px;color:#9aa5c1;margin-bottom:16px}
.cwi-stats span#cwiUsedLabel{font-variant-numeric:tabular-nums}
.cwi-pct{font-weight:800;color:#c7d2fe;font-size:13px}
.cwi-pct.warn{color:#fbbf24}
.cwi-pct.crit{color:#f87171}
.cwi-info-btn{position:relative;width:100%;text-align:left;background:#161d2e;border:1px solid #232b40;border-radius:10px;padding:10px 12px;font-size:12px;color:#8a94ab;cursor:pointer;font-weight:600}
.cwi-info-btn:hover{border-color:#374151;color:#cbd5e1}
.cwi-tooltip{position:absolute;bottom:calc(100% + 10px);left:0;right:0;background:#1a2035;border:1px solid #2a3350;border-radius:10px;padding:12px;font-size:11.5px;line-height:1.6;color:#c3cae0;font-weight:400;text-align:left;opacity:0;visibility:hidden;transform:translateY(4px);transition:opacity .15s,transform .15s;box-shadow:0 12px 30px rgba(0,0,0,.5);z-index:10}
.cwi-info-btn:hover .cwi-tooltip,.cwi-info-btn:focus .cwi-tooltip{opacity:1;visibility:visible;transform:translateY(0)}
.cwi-demo{display:flex;gap:8px;margin-top:16px;border-top:1px solid #1a2130;padding-top:14px}
.cwi-demo button{flex:1;background:#161d2e;border:none;border-radius:8px;padding:8px;font-size:11px;font-weight:700;color:#9aa5c1;cursor:pointer;transition:background .15s}
.cwi-demo button:hover{background:#232b40}var LIMIT = 200000;
var fillEl = document.getElementById('cwiFill');
var usedLabel = document.getElementById('cwiUsedLabel');
var pctLabel = document.getElementById('cwiPctLabel');
function tier(pct) {
if (pct >= 90) return 'crit';
if (pct >= 70) return 'warn';
return 'ok';
}
function setUsage(pct) {
var used = Math.round((pct / 100) * LIMIT);
var t = tier(pct);
fillEl.style.width = pct + '%';
fillEl.className = 'cwi-fill' + (t === 'ok' ? '' : ' ' + t);
pctLabel.className = 'cwi-pct' + (t === 'ok' ? '' : ' ' + t);
pctLabel.textContent = pct + '%';
usedLabel.textContent = used.toLocaleString() + ' / ' + LIMIT.toLocaleString() + ' tokens';
}
document.querySelector('.cwi-demo').addEventListener('click', function (e) {
var btn = e.target.closest('button');
if (btn) setUsage(Number(btn.dataset.pct));
});
setUsage(42);Extend with AI
Take This Snippet Further With AI
The AI prompt for this one is for Patreon supporters ($3 a month), along with a site with no ads. Supporters enter the passcode once and it is remembered in this browser.
What's included
Features
About this UI Snippet
AI Context Window Indicator — Color Bands with a "What Happens Next" Tooltip
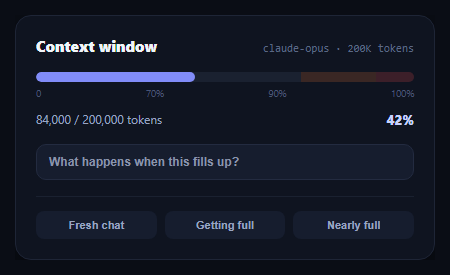
Long AI conversations eventually run into a limit most users don't understand: the context window. This snippet builds a visual indicator, in plain HTML, CSS, and vanilla JavaScript, that shows how full the current conversation's context window is, using color bands to signal safe, warning, and critical zones, plus a hover tooltip that explains in plain language what actually happens once it fills up.
Color bands as a fixed backdrop, fill as the live value
The bar has two layers: static .cwi-band elements mark the warning zone (70-90%) and critical zone (90-100%) as a subtle tinted backdrop, while a separate .cwi-fill element animates its width to the live usage percentage and changes color once it crosses into those zones. Seeing both the current value *and* the zones it's approaching, rather than only a single-color bar, helps a user anticipate the limit before they hit it.
A tooltip that explains consequences, not just numbers
Most usage indicators stop at "70% used" and leave the user to guess what that means. This one includes an info button with a tooltip explaining, specifically, that the assistant will start forgetting the oldest messages once the window fills — the actual behavior users experience as a confusing "why did it forget what I said earlier" moment. Naming the real consequence turns an abstract percentage into something actionable (start a new conversation, or ask for a summary).
Demo buttons simulate a growing conversation
The Fresh chat / Getting full / Nearly full buttons jump between representative usage levels, since a live iframe demo can't accumulate real conversation tokens — a stand-in for what a real integration would update after every model response.
Where this fits in an AI product
Pair it with an AI token usage meter — the context indicator tracks the *current conversation's* window while the usage meter tracks the *billing period's* total consumption, two related but distinct numbers. It also complements an AI chat interface as a persistent header widget, or an AI function call trace in agent products where tool outputs consume context quickly.
Customizing it
Wire setUsage() to your actual token count after each model turn (most APIs report usage in their response), adjust the warning/critical thresholds for your model's real context size, or add an auto-summarize action button that appears once the critical band is reached.
Step by step
How to Use
- 1Paste HTML, CSS, and JSA context window bar renders at 42% usage with safe/warning/critical bands visible.
- 2Click the demo buttonsFresh chat, Getting full, and Nearly full jump the bar between representative levels.
- 3Watch the color shiftPast 70% the fill turns amber; past 90% it turns red, matching the background bands.
- 4Hover the info buttonA tooltip explains what happens to the conversation once the window fills.
- 5Edit LIMIT and thresholdsChange LIMIT to your model's real context size and adjust tier() breakpoints.
- 6Wire up real usageCall setUsage(pct) after each model response using your API's reported token count.
Real-world uses
Common Use Cases
Got questions?
Frequently Asked Questions
A context window is the maximum amount of text (measured in tokens) a model can consider at once, including the full conversation history. Unlike billing usage, which resets monthly, the context window fills up within a single conversation and directly affects what the model can "remember" — which is why it needs a separate, real-time indicator distinct from an account-level usage meter.
Most chat products start truncating or summarizing the oldest messages to make room for new ones once the window fills, which is why users sometimes notice the assistant "forgetting" something said earlier in a long conversation. The tooltip in this snippet states that consequence directly so the percentage isn't just an abstract number.
Rendering the zones as a fixed backdrop lets a user see how close they are to the next threshold even before they reach it — a bar at 60% still shows exactly where the 70% warning zone begins. A single dynamically-colored fill would only reveal the current state, not the upcoming boundary.
Most LLM APIs return usage metadata (prompt and completion token counts) with every response. Sum the running conversation total, divide by the model's actual context window size, and call setUsage(pct) after each turn to keep the indicator live.
Track the current percentage as component state, derive the tier with a small pure function, and bind it to the fill width and color classes. Recompute it whenever new usage data arrives from your chat API's response, typically in the same handler that appends the assistant's reply to the conversation.