


AI Token Flicker Typing Loader — Streaming Token Guess Animation CSS JS
AI Token Flicker Typing Loader · Loaders · Plain HTML, CSS & JS · Live preview
Copy & paste
Source Code
<div class="tf-wrap">
  <div class="tf-bubble">
    <span class="tf-text" id="tfText"></span><span class="tf-cursor"></span>
  </div>
</div>*{box-sizing:border-box;margin:0;padding:0}
body{font-family:system-ui,-apple-system,sans-serif;background:#0b0f1a;min-height:100vh;display:flex;align-items:center;justify-content:center;padding:24px}
.tf-wrap{width:100%;max-width:420px}
.tf-bubble{background:#12162a;border:1px solid #232a45;border-radius:14px;padding:16px 18px;font-size:14px;line-height:1.7;color:#e7e9f5}
.tf-text{white-space:pre-wrap}
.tf-text .tf-settled{color:#e7e9f5}
.tf-text .tf-guessing{color:#5a6180;transition:color .08s}
.tf-cursor{display:inline-block;width:2px;height:16px;background:#818cf8;vertical-align:-3px;margin-left:1px;animation:tfBlink 1s step-end infinite}
@keyframes tfBlink{50%{opacity:0}}// Simulates the look of token-by-token generation: for each upcoming word,
// several plausible "candidate" words flicker rapidly in a dim tone before
// the real word settles into place in full color \u2014 distinct from a plain
// three-dot bounce or a static blinking cursor typing indicator.
var textEl = document.getElementById('tfText');
var FINAL = "Based on your traffic data, mobile users are converting at a noticeably lower rate than desktop, mainly due to a slow checkout form on smaller screens.";
var WORDS = FINAL.split(' ');
var CANDIDATE_POOL = ['analyzing', 'perhaps', 'roughly', 'considering', 'likely', 'checking', 'reviewing', 'possibly', 'estimating', 'comparing'];
function randomCandidates(count) {
var picks = [];
for (var i = 0; i < count; i++) {
picks.push(CANDIDATE_POOL[Math.floor(Math.random() * CANDIDATE_POOL.length)]);
}
return picks;
}
var settledSpan = document.createElement('span');
settledSpan.className = 'tf-settled';
var guessSpan = document.createElement('span');
guessSpan.className = 'tf-guessing';
textEl.appendChild(settledSpan);
textEl.appendChild(guessSpan);
function typeWord(index) {
if (index >= WORDS.length) return;
var real = WORDS[index];
var flickers = randomCandidates(3 + Math.floor(Math.random() * 3));
var f = 0;
var flickerTimer = setInterval(function () {
if (f >= flickers.length) {
clearInterval(flickerTimer);
guessSpan.textContent = '';
settledSpan.textContent += (index > 0 ? ' ' : '') + real;
setTimeout(function () { typeWord(index + 1); }, 90 + Math.random() * 120);
return;
}
guessSpan.textContent = (index > 0 ? ' ' : '') + flickers[f];
f++;
}, 55);
}
setTimeout(function () { typeWord(0); }, 500);Extend with AI
Take This Snippet Further With AI
The AI prompt for this one is for Patreon supporters ($3 a month), along with a site with no ads. Supporters enter the passcode once and it is remembered in this browser.
What's included
Features
About this UI Snippet
AI Token Flicker Typing Loader — A Typing Indicator That Mimics Token-by-Token Generation
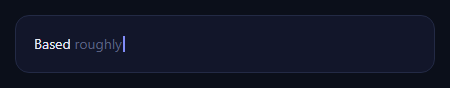
The three-dot bounce is the default typing indicator everywhere, but it communicates nothing about what's actually happening when an AI model generates text token by token. This snippet takes a different approach inspired by that literal generation process: before each real word appears, a handful of dim, rapidly-flickering "candidate" words flash in place, then the actual word settles into full color — visually suggesting the model considering several possible next tokens before committing to one.
Two coexisting spans, not a full re-render
The revealed text lives in .tf-settled, appended to permanently word by word as each one finishes. The currently-flickering word lives in a separate .tf-guessing span appended right after it. Only the guessing span's textContent is replaced on every flicker tick — the settled text is never touched once written, so there's no flash of the whole paragraph re-rendering, only the live edge of generation visibly working.
Randomized flicker count and speed
Each word gets a randomized 3 to 5 "candidate" flickers pulled from a small pool of plausible filler words, each shown for about 55ms before the next candidate replaces it — fast enough to read as machine-speed consideration rather than a deliberate slow reveal. The number of flickers varies per word so the rhythm doesn't feel mechanically identical across the whole sentence.
A real word-by-word reveal loop
typeWord(index) recursively calls itself for the next word only after the current word's flicker sequence completes and is appended to the settled text, with a small randomized pause between words (90ms to roughly 210ms) so pacing feels closer to natural speech cadence than a fixed-interval typewriter.
Distinct from a three-dot bounce or a plain typewriter
A three-dot bounce says only "something is happening." A plain character-by-character typewriter (like the typewriter status log loader) says "text is being revealed" but implies the text is already fully known and just being played back. This flicker pattern specifically suggests uncertainty resolving into a decision per word — a much closer visual metaphor for autoregressive token generation, and a genuinely different read for users familiar with how AI text streaming actually looks and feels.
Customizing it
Replace FINAL with your own real generated sentence, or better, drive typeWord from an actual streaming API response: as each real token/word arrives from your backend, run a short flicker using recent-but-wrong candidate words (or simply the previous partial token) before settling on the true one. Adjust CANDIDATE_POOL, flicker count range, and timing to taste. Pair it with an AI thinking loader for the state before generation begins, switching to this component once the first real token streams in.
Step by step
How to Use
- 1Paste HTML, CSS, and JSA chat bubble appears with a blinking cursor, then word-by-word generation begins.
- 2Watch the flicker per wordSeveral dim candidate words flash rapidly before each real word settles in full color.
- 3Watch the sentence buildSettled words remain fixed while only the live edge keeps flickering.
- 4Reach the endThe cursor keeps blinking after the final word, ready for a real response to follow.
- 5Edit FINAL and CANDIDATE_POOLChange the target sentence and the pool of filler words used for flickers.
- 6Wire up real streamingCall typeWord-style logic from your actual token stream instead of the fixed FINAL string.
Real-world uses
Common Use Cases
Got questions?
Frequently Asked Questions
A three-dot bounce communicates only that something is happening, with no relation to the actual content. This component flickers plausible candidate words in a dim tone before each real word settles in full color, directly visualizing the idea of a model considering multiple possible next tokens before committing \u2014 a much more literal metaphor for how AI text generation actually works.
The revealed sentence lives in a separate .tf-settled span that is only ever appended to, never rewritten. The currently-flickering word lives in its own .tf-guessing span whose textContent is replaced on each tick. Keeping them separate means only the live edge of generation re-renders, not the whole growing paragraph.
Instead of iterating the fixed FINAL string, call your flicker-then-settle logic each time a real token or word arrives from your SSE/WebSocket stream: run a short flicker of a few candidate strings (or the model\u2019s own top alternative tokens, if your API exposes them), then append the real received word to the settled span exactly as typeWord does.
Each word draws a random 3 to 5 candidates from the pool, shown at a fixed fast interval, so the total flicker duration naturally varies word to word. This avoids the identical, robotic rhythm a fixed-count fixed-speed loop would produce across an entire sentence.
Yes \u2014 if your model API exposes alternative token candidates and their probabilities (some do via logprobs), swap CANDIDATE_POOL\u2019s random pick for those real alternatives so the flicker genuinely reflects the model\u2019s own uncertainty rather than decorative filler words.
Yes. Keep settledText and the current guessWord in state, run the flicker sequence inside an effect keyed to the current word index (using setInterval with cleanup), and append to settledText only once the flicker sequence completes \u2014 render both pieces of state as adjacent spans exactly as the vanilla version does.